我的资源
共 246 个数据集
VoxPopuli
Speech RecognitionUnsupervised Representation Learning
VoxPopuli

Introduced by Wang et al. in VoxPopuli: A Large-Scale Multilingual Speech Corpus for Representation Learning, Semi-Supervised Learning and Interpretation

0 下载 · 0 赞获取 →
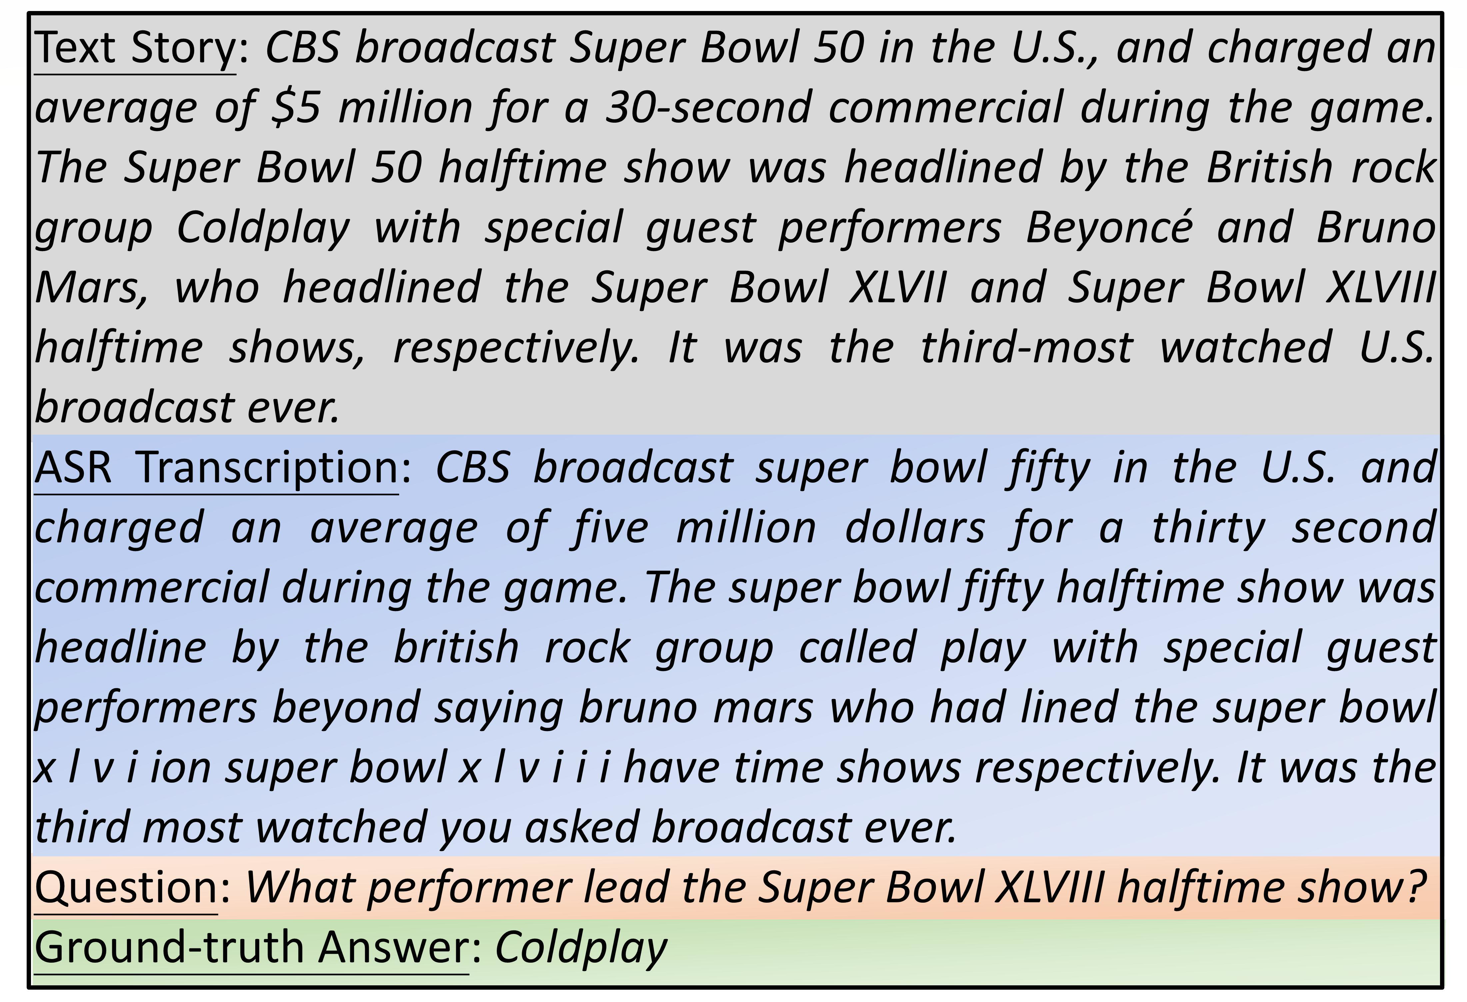
Spoken-SQuAD
Speech RecognitionQuestion Answering
Spoken-SQuAD

Introduced by Li et al. in Spoken SQuAD: A Study of Mitigating the Impact of Speech Recognition Errors on Listening Comprehension

0 下载 · 0 赞获取 →
Switchboard-1 Corpus
Dialogue Act Classification
Switchboard-1 Corpus

The Switchboard-1 Telephone Speech Corpus (LDC97S62) consists of approximately 260 hours of speech and was originally collected by Texas Instruments in 1990-1,

0 下载 · 0 赞获取 →
MaSS
Speech RecognitionSleep Stage Detection
MaSS

Introduced by Boito et al. in MaSS: A Large and Clean Multilingual Corpus of Sentence-aligned Spoken Utterances Extracted from the Bible

0 下载 · 0 赞获取 →
CoVoST
Speech RecognitionCrossLingual Transfer
CoVoST

Introduced by Wang et al. in CoVoST: A Diverse Multilingual Speech-To-Text Translation Corpus

0 下载 · 0 赞获取 →
CN-CELEB
Speaker VerificationSpeaker Recognition
CN-CELEB

Introduced by Fan et al. in CN-CELEB: a challenging Chinese speaker recognition dataset

0 下载 · 0 赞获取 →
AVSpeech
Audio Source Separation
AVSpeech

Introduced by Ephrat et al. in Looking to Listen at the Cocktail Party: A Speaker-Independent Audio-Visual Model for Speech Separation

0 下载 · 0 赞获取 →
WHAMR!
Speech EnhancementAudio Source Separation
WHAMR!

Introduced by Maciejewski et al. in WHAMR!: Noisy and Reverberant Single-Channel Speech Separation

0 下载 · 0 赞获取 →
TIMIT
Speech Recognition
TIMIT

The TIMIT Acoustic-Phonetic Continuous Speech Corpus is a standard dataset used for evaluation of automatic speech recognition systems.

0 下载 · 0 赞获取 →
Europarl-ST
Speech RecognitionMachine Translation
Europarl-ST

Introduced by Iranzo-Sánchez et al. in Europarl-ST: A Multilingual Corpus For Speech Translation Of Parliamentary Debates

0 下载 · 0 赞获取 →
LibriMix
Speech EnhancementSpeech Separation
LibriMix

Introduced by Cosentino et al. in LibriMix: An Open-Source Dataset for Generalizable Speech Separation

0 下载 · 0 赞获取 →
DIHARD II
Speaker Diarization
DIHARD II

Introduced by Ryant et al. in The Second DIHARD Diarization Challenge: Dataset, task, and baselines

0 下载 · 0 赞获取 →