我的资源
共 246 个数据集
AISHELL-6
中文构音障碍数据库中文口吃数据库
AISHELL-6

为了加快技术迭代,快速推动相关项目的研发,希尔贝壳(AISHELL)开源了AISHELL-6A(中文口吃数据库)以及AISHELL-6B(中文构音障碍数据库)。

0 下载 · 0 赞获取 →
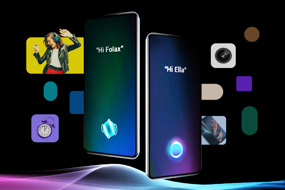
传音持续深耕AI语音多模态技术,打造本地化智能交互体验
AI语音多模态技术
传音持续深耕AI语音多模态技术,打造本地化智能交互体验

伴随着5G、人工智能技术的发展,智能语音已经随着各种智能终端产品渗透到人们的日常生活中,带来了更多便捷和可能性。作为新兴市场智能终端产品和移动互联服务提供商,传音聚焦人工智能领域持续创新,不断推进AI语音技术的研究和应用,挖掘更多本地化用户场景要求,为新兴市场用户带来全场景智能交互体验

0 下载 · 0 赞获取 →
DReaM
Linguistic Descriptions
DReaM

A multilingual corpus of linguistic descriptions of the world's natural languages

0 下载 · 0 赞获取 →
Sound Comparisons
Diversity in Phonetics
Sound Comparisons

A database to explore diversity in phonetics across language family

0 下载 · 0 赞获取 →
Kashmiri Data Corpus
Speech Recognition
Kashmiri Data Corpus

An audio and text corpus for the Kashmiri language

0 下载 · 0 赞获取 →
TED-LIUM Release 3
speech recognition
TED-LIUM Release 3

TED-LIUM corpus release 3

0 下载 · 0 赞获取 →
Hi-Fi TTS
Speech Synthesis
Hi-Fi TTS

Hi-Fi Multi-Speaker English TTS Dataset (Hi-Fi TTS) is a multi-speaker English dataset for training text-to-speech models

0 下载 · 0 赞获取 →
CN-Celeb
Speaker Identification
CN-Celeb

A Free Chinese Speaker Recognition Corpus Released by CSLT@Tsinghua University

0 下载 · 0 赞获取 →
Opencpop
singing voice synthesis
Opencpop

A publicly available high-quality Mandarin singing corpus, is designed for singing voice synthesis (SVS) systems.

0 下载 · 0 赞获取 →
JTubeSpeech
Speech Recognitionspeaker verification
JTubeSpeech

Corpus of Japanese speech collected from YouTube

0 下载 · 0 赞获取 →
OpenSTT
Speech Recognition
OpenSTT

Russian Open Speech-to-Text Dataset

0 下载 · 0 赞获取 →
The People’s Speech
Speech Recognition
The People’s Speech

A Large-Scale Diverse English Speech Recognition Dataset for Commercial Usage

0 下载 · 0 赞获取 →