
 新一代Kaldi
经过 Dan 长时间以来对声学模型的持续优化,我们终于确定了新版的 Zipformer 结构,并提交代码至:
快:收敛快;计算快
稳:半精度训练稳定
准:识别精度高
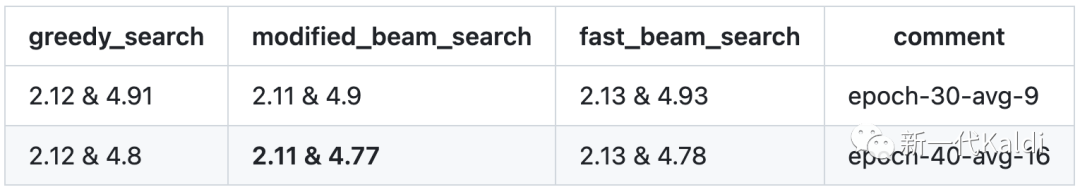
不同参数规模的模型表现
normal-scaled model (65.5 M), max-duration=1000, ~1h7m per epoch on 4 * V100-32GB gpus
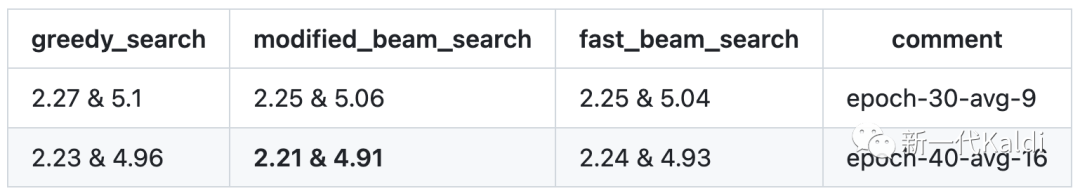
small-scaled model (23.2M), max-duration=1500, ~1h30m per epoch on 2 * V100-32GB gpus
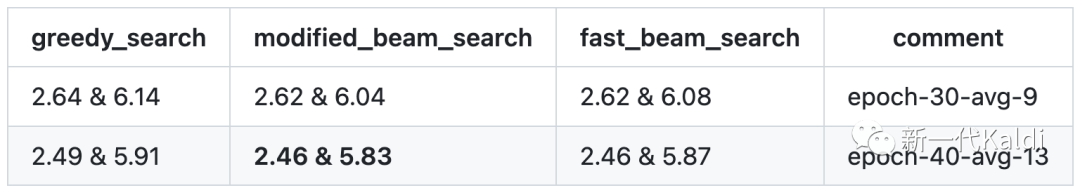
large-scaled model (148.4M), max-duration=1000, ~1h20m per epoch on 4 * V100-32GB gpus
与 icefall 中现有的模型比较
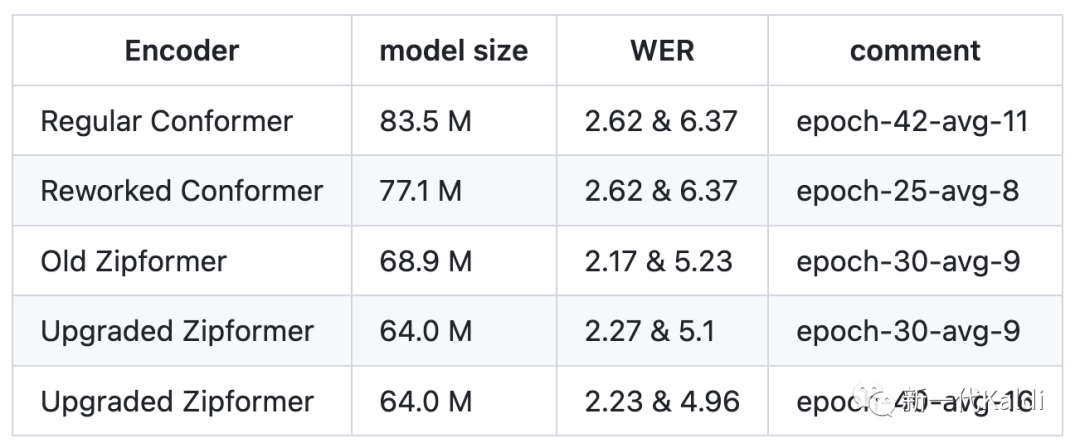
regular Conformer, 83.5 M (pruned_transducer_stateless[2])
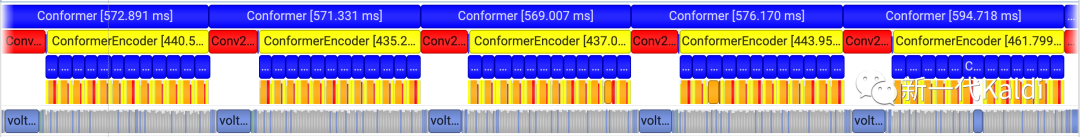
reworked Conformer, 77.1 M (pruned_transducer_stateless2[3])
old Zipformer, 68.9 M (pruned_transducer_stateless7[4])
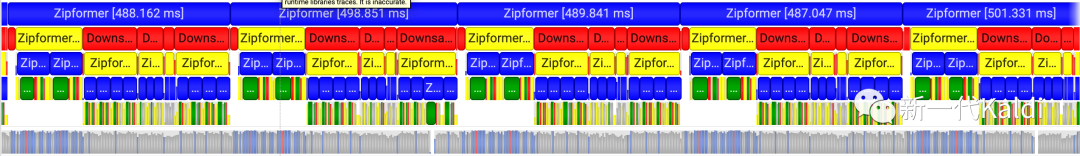
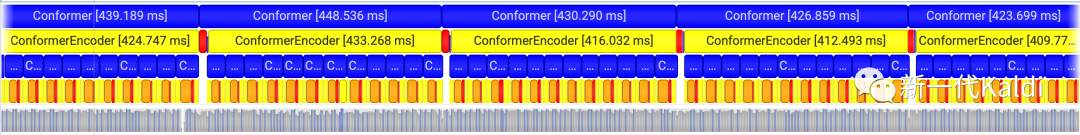
upgraded Zipformer, 64.0 M
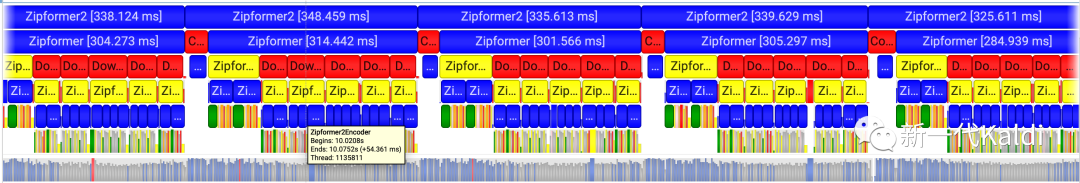
与 SOTA 模型比较
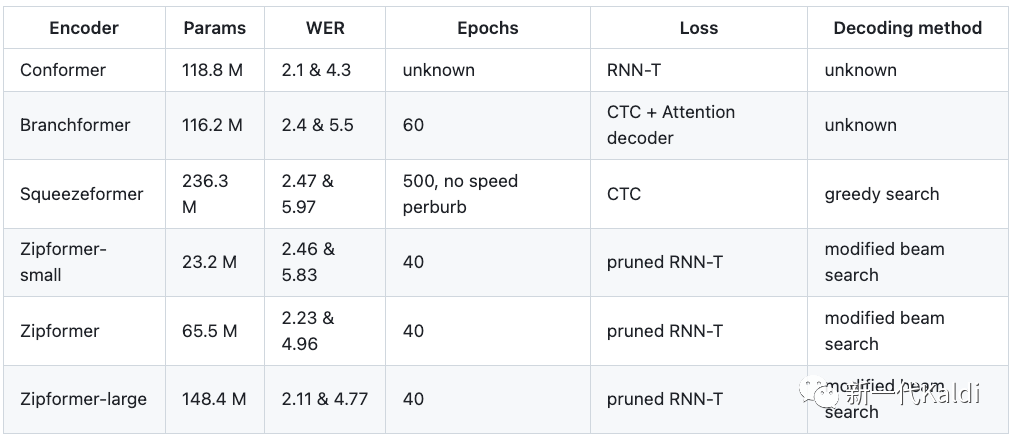
我们将 Zipformer 与现有的 SOTA 模型比较,包括Conformer[5]、BranchFormer[6]、SqueezeFormer[7]。下表展示了不同模型在 LibriSpeech 数据集 test-clean & test-other 的 WER。数据摘自原论文,没有作说明的标记为 unknown。 可以看出,相比较其他 SOTA 模型,Zipformer 的识别精度更加逼近Conformer 原论文的结果。
流式模型表现
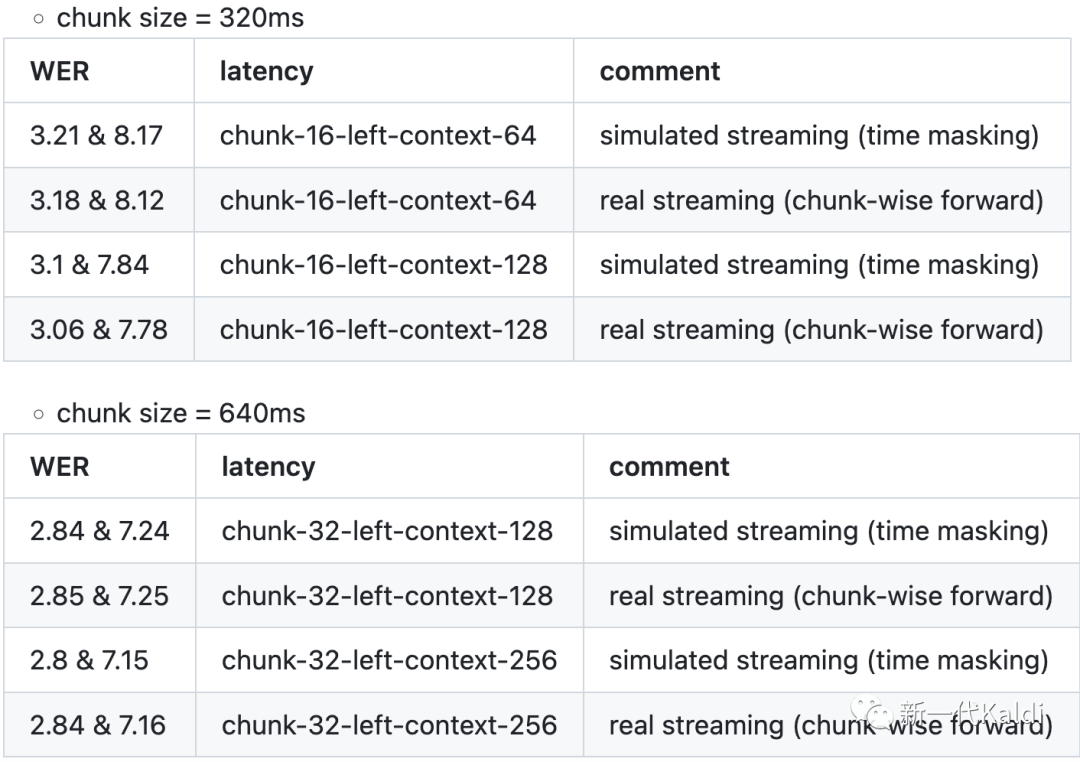
The chunk size is at 50Hz frame rate
后续计划
我们将着重维护以及引导用户重点使用这个新的 recipe,并陆续添加其他特性,如 CTC + Attention decoder 框架,多数据集训练, language model rescoring, delay penalty, 等等。
为其他数据集添加 zipformer recipe,如 AiShell、WenetSpeech。
支持服务端模型部署,包括sherpa[8]、sherpa-onnx[9]、sherpa-ncnn[10]。
参考资料
[1]nvtx: https://nvtx.readthedocs.io/en/latest/
[2]pruned_transducer_stateless: https://github.com/k2-fsa/icefall/tree/master/egs/librispeech/ASR/pruned_transducer_stateless
[3]pruned_transducer_stateless2: https://github.com/k2-fsa/icefall/tree/master/egs/librispeech/ASR/pruned_transducer_stateless2
[4]pruned_transducer_stateless7: https://github.com/k2-fsa/icefall/tree/master/egs/librispeech/ASR/pruned_transducer_stateless7
[5]Conformer: https://arxiv.org/pdf/2005.08100.pdf
[6]BranchFormer: https://arxiv.org/pdf/2207.02971.pdf
[7]SqueezeFormer: https://arxiv.org/pdf/2206.00888.pdf
[8]sherpa: https://github.com/k2-fsa/sherpa
[9]sherpa-onnx: https://github.com/k2-fsa/sherpa-onnx
[10]sherpa-ncnn: https://github.com/k2-fsa/sherpa-ncnn
